setting a new standard for sheet music scanning
we're releasing copista-mini: a sheet music scanning model that performs 6x more accurately than the next released model on real quartet scans, at just 1/30 of the size of the next best model. It's open weight, so you can run it on your own hardware, too.
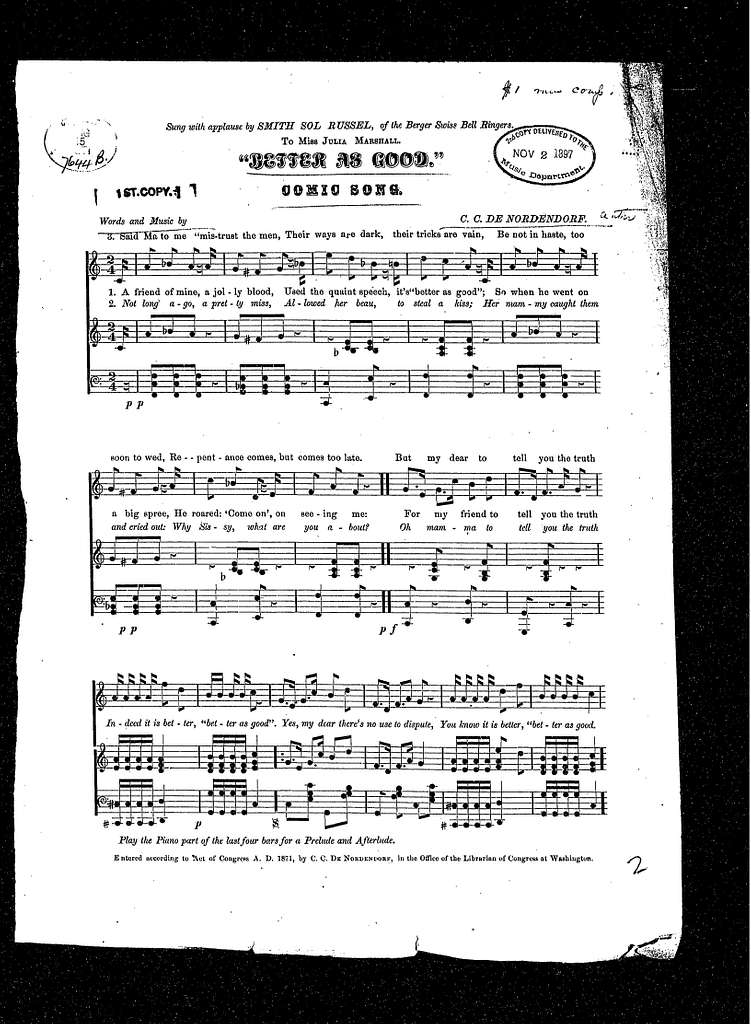
Pages printed in the 1800s and 1900s, as they were scanned, and what copista-mini read from each. Click a line to see another, and press play on the score to hear it.
we ran the model on a few sets of benchmarks. to make the comparison fair, i used the legato paper's test sets and scoring. the paper scores with OMR-NED, which measures the edits it takes to turn the model's output into the score it should be (notes, rests, beams, slurs, dynamics, and so on). the charts show it as an error rate, so lower is better. i used three sets, and all of them are authentic scans. they're OpenScore String Quartets (252 pages), OpenScore Lieder (55 pages), and Polish Scores (112 pages). the Lieder set actually has 64 pages. But 9 of them have ground truth without the vocal staff, so i left those out. copista-mini and copista-micro are copista-28m and copista-2m on hugging face. i ran audiveris, homr and transcoda myself. legato's numbers are self-reported, and legato 2 isn't released, so i used the numbers from its paper.
error rate (%)← lower is better
OpenScore String Quartets
legato 2 is not released: its figures are from its paper
OpenScore Lieder
Polish Scores
size (parameters)
the llama image encoder legato comes packaged with
copista's harness
most previous models are trained on synthetic renders (plus some wrinkles), and they do well on those. but give them an authentic scan from the 1800s or 1900s, and they collapse. i focused ours on real scans, and there's a few technical reasons why it doesn't.
first is the training data. i render each training page from a public domain score, and each page rolls a different engraving style (font, spacing, line weights, page layout). on half of the pages, i also nudge that style a bit. the handwritten pages use handwritten symbols from 50 different writers. on top of that, there is a scan simulation with warped paper, uneven lighting, patchy ink, blur, noise and jpeg artifacts. so to the model, an authentic scan is another variation of a page it hasn't seen yet.
another reason is the way the score gets written. most other models read the page and generate the score as text, one token at a time (legato uses abc notation). i think of it kind-of like a chatbot typing out the score. if it misreads a note early on, the rest of the page can drift, and there is nothing checking if a bar adds up. ours never generates the score directly. instead, it finds each symbol on the page in one pass, with the staff position, stem and dots of each note. then, the harness builds the score from those symbols.
the last reason is the harness. honestly, the harness is basically a solver. it tries different readings of the page, and picks the one with the fewest warnings. critical errors have to be resolved no matter what, for instance a bar that is too long or short for its time signature, or parts that are out of line. minor warnings, like notes a semitone apart, only get resolved if the fix costs less than the warning. to resolve a bar, it can re-read the bar at a different size. also, it can ask a tiny model (around 1m params) that reads the bar next to the other parts. the rules themselves were developed with ai (..how that worked goes here..).
error rate (%)← lower is better
legato
legato 2
legato 2 is not released: its figures are from its paper
copista-micro
copista-mini
it works for some handwritten scores. but honestly, if even you have trouble reading one, the model will too.
this is the initial release of the model. in the coming months, we plan to scale the model and improve the harness. Our end-goal is to be able to accurately and faithfully scan the public massive libraries of scores at universities and libraries.
the weights are on hugging face, as copista-28m and copista-2m. copisteria, the harness that builds the score from what they find, is on github.